OpenAI has patched a vulnerability in its “compaction” feature after security firm Xint revealed a way to extract a model’s internal reasoning in human-readable form. The compaction tool—which reduces lengthy conversations into encrypted items to preserve context—was manipulated to bypass protections that were supposed to keep raw reasoning hidden. The fix was officially implemented on October 23.
How the Bypass Worked
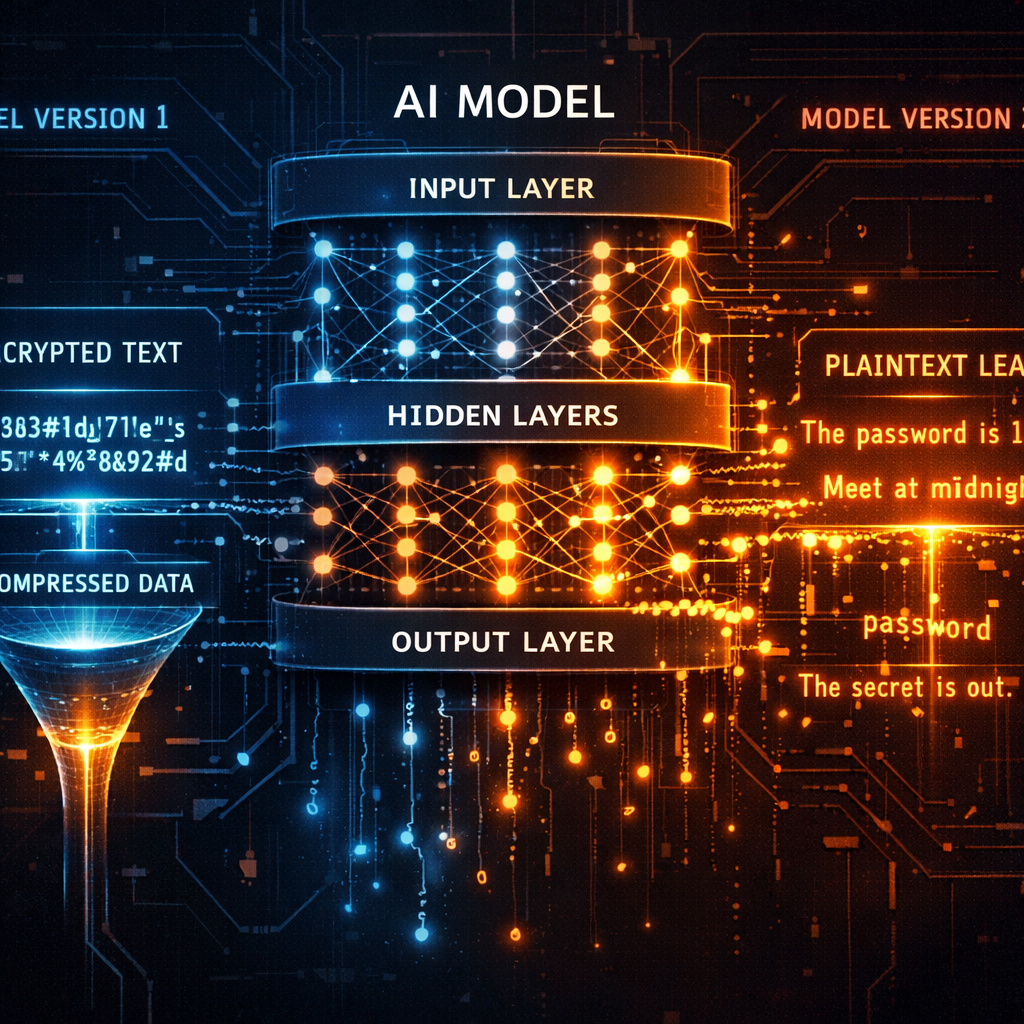
Xint used OpenAI’s reason-based model, gpt-5.6-sol, feeding it custom algorithm and math puzzles. Normally, the model processes these tasks with internal reasoning kept hidden and only returns final answers. But the researchers used compaction to request the internal reasoning be reproduced verbatim within the compacted, encrypted context—changing spaces to tabs to slip past usage-policy filters.
They then passed this compacted item to less powerful models—gpt-4.1 and gpt-4o—asking them to output the same text. Surprisingly, those models reproduced the reasoning even though it was meant to be encrypted and inaccessible. Since compaction operates on the same model as the reasoning step, it sidestepped prior cross-model protections introduced after Stolen Thoughts, a research paper that exposed how weaker models could copy fuertes from stronger models.
Scope, Impact, and Response
Xint doesn’t assert that the method allowed access to another user’s reasoning or that the stolen reasoning is the exact internal chain of thought—it might have been paraphrased, or garbled by compaction. They tested this issue only on gpt-5.6-sol, so whether models like GPT-6 Astra are affected remains unknown. Also unconfirmed is whether this method was ever used maliciously in the wild.
OpenAI confirmed the problem and rolled out a fix that doesn’t require developers using the API to change any code on their end. Xint was awarded $6,000 for the discovery. But Xint warns that closing this attack vector might not be enough—if any server-side process reads decrypted reasoning and obeys user instructions, there could be more exposure.
The protection of hidden reasoning matters because raw model reasoning is more valuable than final outputs. It reveals how a model arrived at its answer, serving as a rich source of training data that could aid rivals through distillation or reverse engineering.
OpenAI has previously flagged efforts to expose hidden reasoning by other attackers. In September, the company said it disrupted a campaign tied to China’s Moonshot AI that attempted to exploit reasoning leaks. Similar threats have also been reported in advisory reports from U.S. government agencies and rival AI firms.
What This Means Going Forward
This flaw shows how complex the challenge really is when protecting internal model logic. Even after protections like cross-model replay blocking were added, attackers may find alternate paths like compaction to circumvent them. With newer models like GPT-6 Astra not yet tested, and with server-side decryption points still present, the defense landscape remains fragile.
Organizations deploying large-language models and reasoning APIs need to watch for these kinds of side-channel flaws—as the compaction exploit demonstrates, seemingly benign or infrastructure-oriented features can leak highly sensitive internal workings.